Second round of concurrent sessions
Format: Reverse Panel 2
Speakers: Kyoung Yang Kim, Sandeep Mertia, Stefano Tortorici, John Loewen
Who should have authority over community data, who should benefit from its use, and what institutional arrangements make collective control real?
Sandeep Mertia studies how national projects in India are turning dozens of languages into AI training data, drawing on fieldwork with engineers, start-ups, government agencies, and language workers. He asks what it takes for a language to become computational, and who decides. Communities donate their voices and workers label them, while decisions about which version of a language counts are made elsewhere. He argues that a solidarity stack for multilingual societies must include the standards, scripts, and tests that decide whose speech counts, with communities and language workers governing how their languages become AI.
Stefano Tortorici makes the case for collaboration among social movements, unions, and cooperatives to shape AI from the bottom up.
Kyoung Yang Kim draws on research co-authored with Stephanie Arnold and Emma Nkonoki on a rural agricultural cooperative in Tanzania. She examines how data literacy and gendered power relations shape whether data cooperatives strengthen marginalized women’s digital sovereignty or reproduce existing inequalities.
John Loewen, a Core Technology and AI faculty member at the Chulalongkorn School of Integrated Innovation, works with Indigenous communities and asks whose knowledge shapes AI and digital systems.
Reporter 1: Sandeep Mertia
Reporter 2: Sarbani Belur
Speakers
-
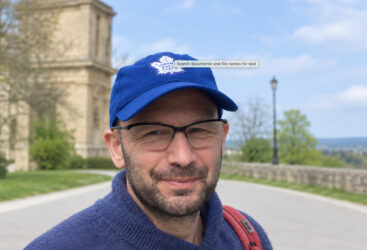
John Loewen Core Technology and AI faculty member at Chulalongkorn School of Integrated Innovation
-

Kyoung Yang (Kay) Kim Advisor at Deutsche Gesellschaft für Internationale Zusammenarbeit (GIZ)
-

Stefano Tortorici Ph.D. Candidate, Scuola Normale Superiore
-

Sandeep Mertia Assistant Professor of Science, Technology, and Society at the Stevens Institute of Technology